
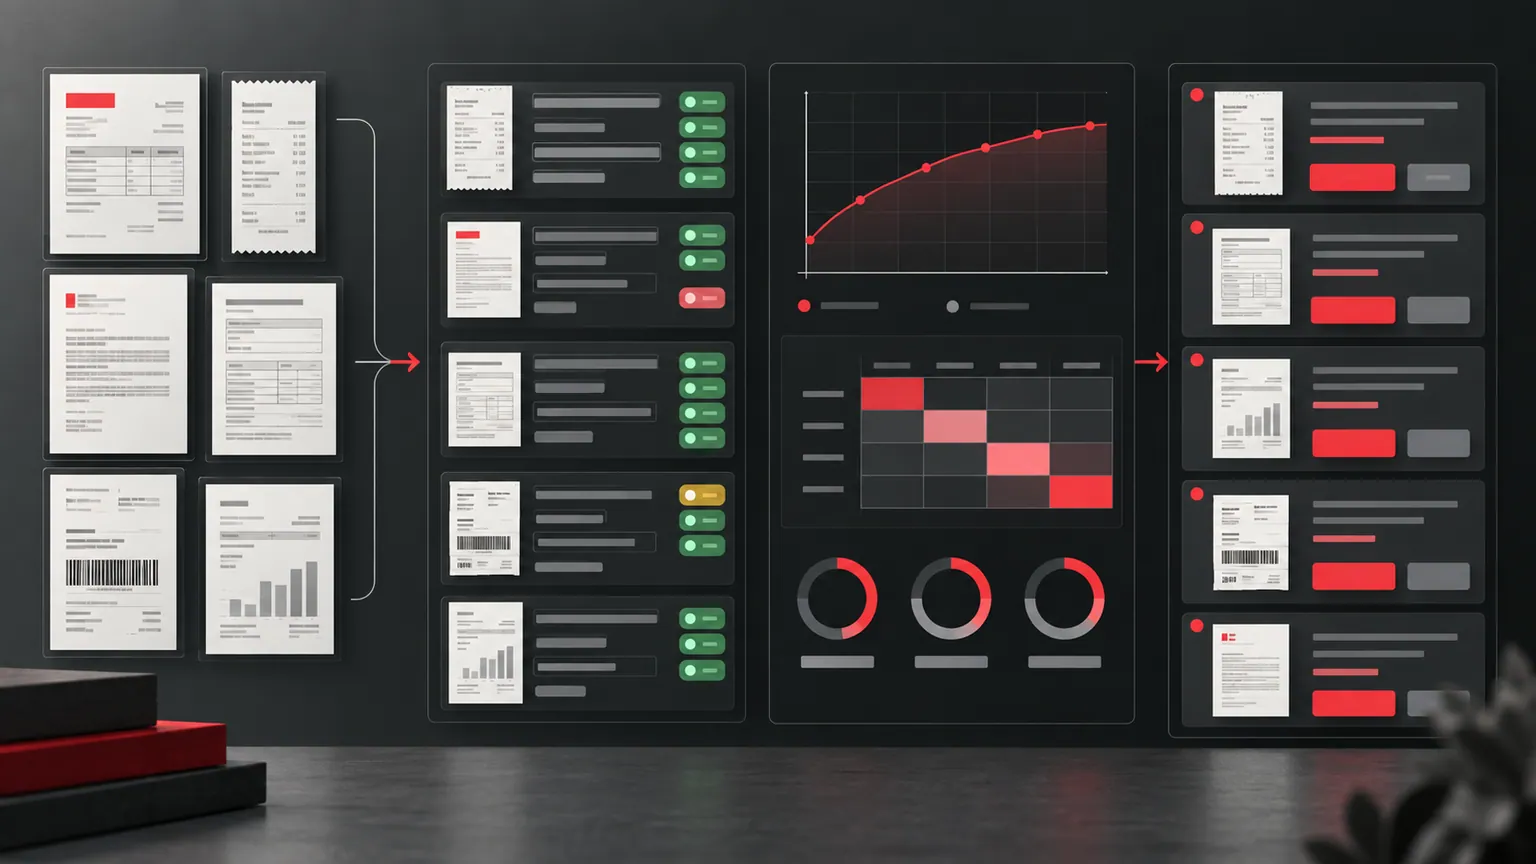
An AI feature is only useful if its behaviour is measurable and its limits are understood. Before any document extraction feature reaches production, we build an evaluation set: a labelled sample of real cases, scored before and after every model change.
Building the evaluation set
Pull a representative sample of the documents the feature will actually see, including the messy ones — poor scans, unusual layouts, missing fields. Label the correct answer for each field by hand. This set is what tells you whether a model change is an improvement or a regression, rather than relying on impressions from a handful of examples.
Setting a human review threshold
Low-confidence output should route to a person rather than be acted on automatically. The threshold is not a one-off decision — tune it against the evaluation set until the false-positive rate is one you are willing to accept in production.
What good looks like
A production-ready extraction feature has a documented accuracy figure against a real sample, a review queue for anything below threshold, and an audit trail of what was extracted and where it came from.
Related service: Business AI integration.
